In this Field Note
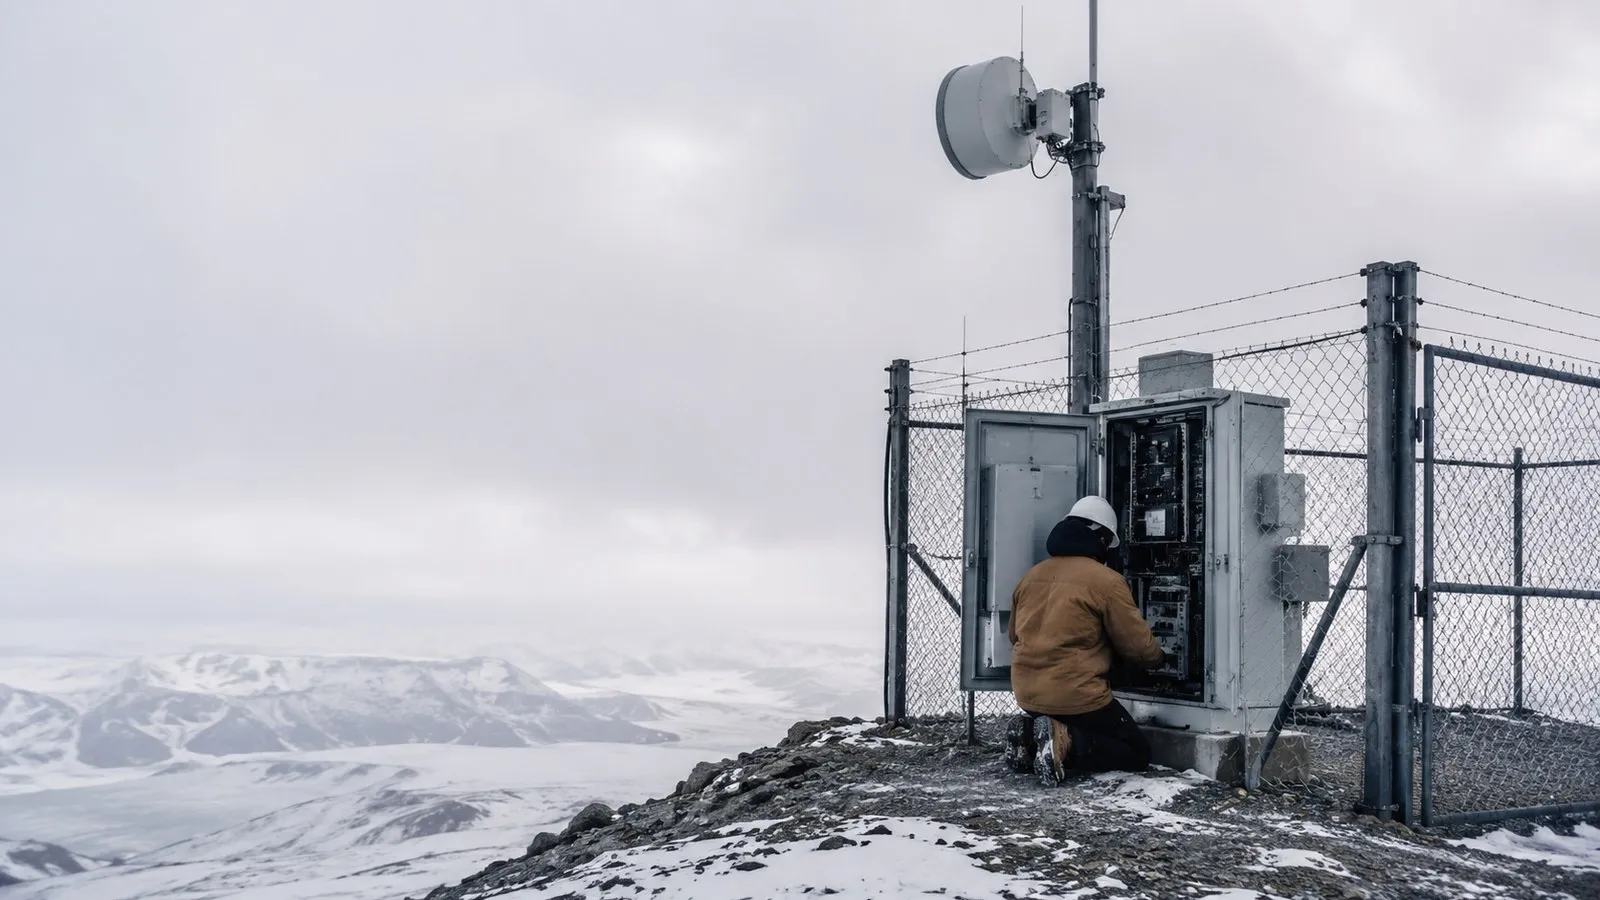
The replacement radio is on the shelf. Unfortunately, its power supply is in another building, the correct configuration is on somebody’s laptop, and the person who knows the gate code is on vacation.
You own a spare part. You do not yet own a quick repair.
At a remote site, the delay between finding a fault and restoring service can cost more than the failed equipment. Design the recovery while the system is on the bench, where a missing adapter is mildly irritating rather than a reason to drive back down the mountain.
Time the whole repair
Break recovery into the stages a real person must complete: detection, diagnosis, authorization, preparation, access, travel, replacement, and verification. Write down the uncertainties as well as the optimistic durations.
Here is an illustrative timeline, not a claim about a particular site:
| Stage | Unprepared example | What could shorten it |
|---|---|---|
| Identify the likely failure | 45 minutes comparing incomplete observations | Power, transport, and device history available before dispatch. |
| Assemble the right kit | 60 minutes finding files and accessories | A checked replacement set with a current procedure. |
| Travel and gain access | 120 minutes | A realistic access plan; some delays may be unavoidable. |
| Replace and restore | 45 minutes | A rehearsed configuration and labeled connections. |
| Verify the service | 30 minutes | Agreed tests and an available service owner. |
The example totals five hours. Saving twenty minutes on the physical swap helps, but preparation and diagnosis offer substantial opportunities too. If the site is inaccessible in certain conditions, better instructions cannot wish that constraint away; an independent path or local contingency may be necessary.
Use the timeline to choose investments. A modest spare set can be enough for a low-impact convenience link. A site whose loss stops operations needs a more demanding recovery plan. The appropriate answer depends on consequence and access, not on how impressive the spare cabinet looks.
Collect evidence before sending the truck
When a site goes silent, distinguish what is known from what cannot be observed. If the upstream transport is down, the downstream switch may be healthy, failed, or without power. “Unreachable” does not decide between them.
Retain trends in supply condition, temperature, radio quality, interface errors, and resets. An increasing error count or declining receive level before the outage can help determine what equipment and expertise to send. It does not eliminate the need to verify the diagnosis on site.
Consider whether a separate management route is worth its cost. A different VLAN on the same backhaul shares the transport failure. Cellular access has its own dependencies, including coverage, antenna position, reserve power, carrier service, and security. Test the installed arrangement rather than assuming that a modem’s presence establishes independence.
Make the loss of monitoring visible. A stale graph should be clearly stale; otherwise the last good reading can continue delivering excellent news long after the site has stopped supplying it.
Make remote power control deliberate
A controllable PoE port or power outlet can avoid a visit when restarting a particular communications device is an appropriate recovery action. It also introduces a control that can disconnect useful equipment, so give it accurate labels, restricted access, and a documented purpose.
Confirm the device’s exact supply requirements and the power source’s capabilities. MikroTik’s PoE-Out documentation, for example, describes model-dependent behavior, supply compatibility, telemetry, and power-cycle functions. A familiar connector does not establish compatible voltage, polarity, or power delivery.
Check that the controller remains reachable while the target is off. Record the normal restart interval, what a successful return looks like, and when to stop and escalate. Rebooting again before a slow device has finished starting can turn a recoverable fault into a long afternoon.
I generally leave ping watchdogs disabled unless a known failure mode justifies one. If automation is necessary, the target must distinguish that failure from a problem farther upstream. Allow for normal loss and startup, bound repeated actions, and keep a reset history. An unavailable internet host is not evidence that a local radio needs its power removed.
Keep this discussion separate from process equipment. Cycling a communications device and cycling machinery or operational controls involve different authority and consequences.
Prepare a replacement set
For each critical equipment role, identify a tested replacement and everything needed to make it useful. Include compatible software, the appropriate restore files, licenses or certificates, optics, power hardware, mounting accessories, console adapters, and the procedure.
Decide which configuration can be loaded in advance and which site-specific details must be applied during installation. A shared spare may need a controlled selection process so the wrong site’s identity is not restored. Keep secrets protected, with a reliable way for authorized staff to obtain them.
Confirm backup behavior against the platform documentation. RouterOS system backups are one example of a recovery format with platform-specific restoration considerations. Do not assume a file transfers safely between different hardware or software simply because the import dialog accepts it.
Label accessories with their role and compatibility. Date the check. Decide who refreshes the spare after production changes. A replacement prepared correctly two years ago may have become a small museum of obsolete assumptions.
Run a spare drill
Choose one representative device and rehearse away from production. Give the procedure and replacement set to a competent person who did not assemble them. Time the exercise from opening the instructions to passing the agreed tests.
- Confirm the replacement’s identity, hardware, and software against the procedure.
- Restore the approved configuration while isolated from the live network.
- Verify management access, interface mapping, and the required service behavior in the test environment.
- Check the rollback and escalation instructions without relying on the author’s memory.
- Record missing items, unexpected prompts, actual timings, and anything the bench test cannot prove.
Do not attach a cloned device to production with duplicated addresses or identities. A lab result also does not certify the physical RF path, field power system, or access arrangements. Record those remaining acceptance tasks separately.
Update the recovery runbook from the drill. Its next reader should benefit from the surprises you found.
Buy recovery you can use
Start with the failure whose consequences and repair delay worry you most. A timed rehearsal will often identify a more precise next purchase than a general request for “more redundancy.” Sometimes the missing item is hardware. Sometimes it is a working credential, an access agreement, or a configuration nobody has tried to restore.
Oaktown Tech can help design and hand off remote infrastructure with those recovery details included. The objective is straightforward: when somebody has to travel, they should know why they are going and have a credible way to finish the job.
Join the discussion